This guide describes the DOCA VNet PCI Device reference application in doca/applications/vnet_pci_dev.
Introduction
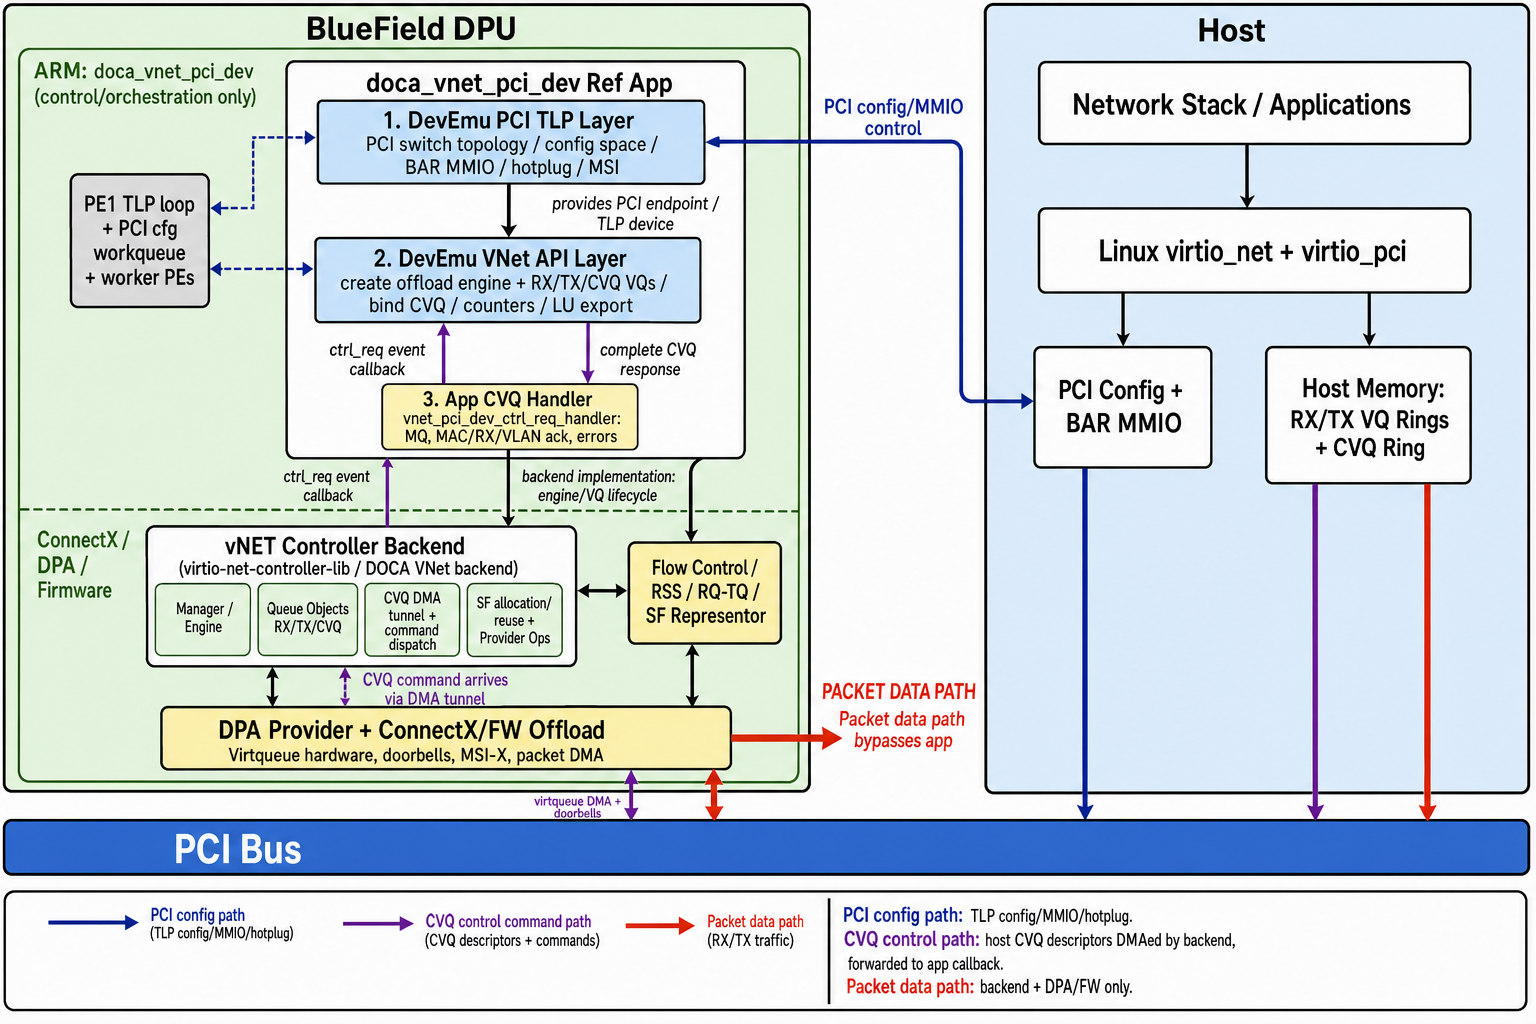
The DOCA VirtIO-net PCI Device Application emulates one or more virtio-net PCIe endpoints on NVIDIA BlueField DPUs. The application uses DOCA DevEmu PCI TLP APIs to emulate PCIe configuration/MMIO behavior and DOCA DevEmu VNet APIs to provide the hardware-backed VirtIO network datapath.
The host sees standard virtio-net PCI devices behind a software PCI switch topology. The DPU application owns PCI enumeration behavior, VirtIO PCI BAR emulation, MSI/MSI-X handling, hotplug signaling, queue lifecycle, control virtqueue handling, SR-IOV, and optional live update handover.
System Design
Host Side (Virtio-net Client Driver)
The host runs the standard Linux virtio_net driver.
Host responsibilities include:
-
Enumerating the emulated PCI switch and VirtIO-net endpoints.
-
Negotiating VirtIO feature bits.
-
Programming VirtIO common config registers.
-
Allocating and configuring RX/TX virtqueues.
-
Configuring MSI-X vectors.
-
Sending queue notifications through the notify BAR.
-
Sending control virtqueue commands, especially multi-queue commands such as
VIRTIO_NET_CTRL_MQ_VQ_PAIRS_SET.
The host network interface appears as a normal Linux NIC and can be inspected with tools such as ip link, ethtool, and lspci.
BlueField DPU (DOCA Virtio-net Emulation Application)
The DPU runs doca vnet_pci_dev.
The application:
-
Creates a DOCA VNet PCI TLP device type.
-
Creates a software PCI topology with one upstream port, several downstream ports (one downstream port per endpoint), and one VirtIO-net endpoint per downstream port.
-
Handles PCIe Config Read/Write and MMIO Read/Write TLPs.
-
Emulates VirtIO PCI modern capabilities and network device configuration.
-
Creates one DOCA VNet offload engine per endpoint.
-
Creates RX/TX virtqueue objects and an optional control virtqueue.
-
Uses a PCI config workqueue and worker progress engines to keep the main TLP progress loop responsive.
-
Supports static endpoint creation and runtime hotplug/unplug.
-
Supports active/standby live update through
--lu-mode.
Data Path Provider
Unlike the vblk refapp, the vnet refapp does not expose a --provider DPA|DPU flag.
The packet datapath is provided by DOCA DevEmu VNet offload and the underlying NIC/firmware path after the VirtIO queues and offload engine are configured. The application itself is mostly a PCI/VirtIO control-plane and lifecycle orchestrator. It does not implement a userspace packet copy loop for RX/TX data queues.
End-to-End Flow
device_status (host writes)   RESET(0)-> ACK(1)-> DRIVER(3)-> FEATURES_OK(0xB)-> DRIVER_OK(0xF)-> OPERATIONAL
                                                                |                    |
                              (DPU, async on FEATURES_OK)       |   (DPU, async on DRIVER_OK)
                              engine start; create RX/TX VQs;   |   apply VQ shadow + start VQs;
                              create CVQ IO ctx (if MQ)         |   bind CVQ; enable engine; stats
 host writes 0  -> device_status held at NEEDS_RESET(0x40) until async controller cleanup completes -> 0
-
The DPU application starts and creates the PCI TLP type, TLP channel, software PCI topology, and VirtIO-net device model.
-
In static mode, endpoints are created immediately. In hotplug mode, endpoints are created after
plug <idx>. -
The host enumerates the PCI topology and discovers VirtIO-net endpoints.
-
The host
virtio_netdriver reads features and device configuration such as MAC, MTU, link status, speed, duplex, and maximum queue pairs. -
The driver writes VirtIO status bits:
ACKNOWLEDGE,DRIVER,FEATURES_OK, andDRIVER_OK. -
On
FEATURES_OK, the DPU prepares the offload engine, creates VQ objects, and creates the CVQ IO context if multi-queue is negotiated. -
On
DRIVER_OK, the DPU applies queue configuration, starts VQs, binds CVQ, and enables the offload engine. -
Packet RX/TX proceeds through the DOCA VNet offload datapath.
-
Runtime CVQ commands can adjust the number of active queue pairs.
-
Reset, hotplug, unplug, shutdown, and live update paths tear down or transfer state while preserving PCI/VirtIO correctness.
Application Architecture
Core Components
Key files:
-
vnet_pci_dev.c:main(), logging, signal handling, arguments registration, top-level config. -
vnet_pci_dev_core.c: application orchestration, topology setup, controller lifecycle, VirtIO status callback, hotplug, MQ handling, progress loop. -
vnet_pci_device.c: PCI config workqueue, TLP channel callback, config-space emulation, MMIO emulation, VirtIO PCI device model. -
vnet_pci_device.h: public interfaces, BAR layout, queue limits,struct vnet_pci_device. -
vnet_pci_dev_core.h:struct vnet_pci_dev_config,struct vnet_pci_dev_controller, feature defaults. -
pci_spec_tlp.h: PCI/TLP constants, topology macros,struct tlp_context,struct pci_device_config. -
vnet_virtio_types.h: VirtIO-net structures, status bits, feature bits, CVQ command definitions. -
vnet_pci_dev_lu.candvnet_pci_dev_lu.h: live update active/standby handover.
Important data structures:
-
struct tlp_context: global TLP/PCI state, DOCA device, PCI type, TLP channel, PE1, topology, BDF map, ACG queue, VirtIO devices, VNet controllers, and runtime parameters. -
struct vnet_pci_device: one per endpoint; holds VirtIO common config, network config, feature state, VQ shadow array, reset generation, and status callback. -
struct vnet_pci_dev_controller: one per endpoint; owns the DOCA VNet offload engine, RX/TX VQ arrays, CVQ, VNet IO context, worker PE, counters/stats, and atomic lifecycle state. -
PCI config workqueue: moves slow operations away from the main TLP progress loop.
-
PE1: main progress engine for TLP handling.
-
PE2: per-controller worker progress engines used by the workqueue and CVQ IO contexts.
Virtio-net Device Model
The app models a modern VirtIO-net PCI endpoint.
Each endpoint exposes:
-
VirtIO PCI vendor/device IDs.
-
PCI class code for network controller.
-
PCIe capability.
-
MSI-X capability.
-
VirtIO common config capability.
-
VirtIO notify capability.
-
VirtIO ISR capability.
-
VirtIO device config capability.
-
VirtIO PCI config access capability.
The network device config contains:
-
MAC address.
-
Link status.
-
Maximum virtqueue pairs.
-
MTU.
-
Speed.
-
Duplex mode.
-
RSS-related size/hash fields.
The base MAC comes from --mac-addr. Per-endpoint MACs are generated by incrementing the last octet by the endpoint index.
Virtio Queues
RX VQ = qp*2   TX VQ = qp*2+1   CVQ = max_qp*2   Total VQs = 2*max_qp+1
default max_qp=8   hard max=127   initial active qp=1   queue size default 1024, 16..4096, power-of-two
Queue model:
-
RX VQ index:
queue_pair_index * 2. -
TX VQ index:
queue_pair_index * 2 + 1. -
CVQ index:
max_queue_pairs * 2. -
Total VQs:
max_queue_pairs * 2 + 1.
Defaults and limits:
-
Default max queue pairs:
8. -
Maximum queue pairs:
127. -
Initial active queue pairs:
1. -
Default queue size:
1024. -
Queue size range:
16-4096. -
Queue size must be a power of two.
The application maintains a shadow copy of host-programmed VQ config in struct vnet_pci_device. Worker threads snapshot this shadow state before applying it to DOCA VQs, avoiding races with reset.
PCIe TLP Emulation
The application handles PCIe TLPs directly.
TLP handling flow:
-
vnet_pci_dev_event_cb()receives a TLP channel request. -
ACG requests are cached for later MSI Memory Write TLPs.
-
PCI event requests are completed directly.
-
Normal requests are classified as config read/write, memory read/write, or unsupported.
-
The target device is resolved through BDF lookup or BAR address lookup.
-
Endpoint TLPs are protected with an endpoint read lock (to avoid racing hot-unplug destruction).
-
Config-space and MMIO handlers generate the correct completions.
-
Invalid/unmapped requests return Unsupported Request through the dummy device path.
The app emulates both Type 0 endpoint config space and Type 1 bridge config space.
PCI Switch Topology
The topology is:
USP -+- DSP[0] - EP[0]      USP: upstream port (Type-1)   DSP: downstream port per EP (Type-1 + HP slot)
     +- DSP[N] - EP[N]      EP: virtio-net (Type-0)       DUMMY: Unsupported Request for invalid BDFs
DUMMY device for unsupported BDF routing
Components:
-
USP: upstream switch port, root of the software switch. -
DSP: downstream switch port, one per endpoint, with PCIe hotplug slot capability. -
EP: VirtIO-net endpoint. -
DUMMY: returns Unsupported Request for invalid probes.
The host assigns bus/device/function numbers during enumeration. The app caches BDF mappings and updates them on bus renumbering.
SR-IOV
A PF can expose up to 64 independent virtio-net VFs, each with its own config space, MSI-X vectors, doorbells, offload engine and SF datapath, usable on the host or passed through to a VM. Enabled with --total-vfs. Full design in §7.7.
Threading & latency model (core invariant)
PE1 (main thread): services host config/MMIO TLP completions, < 1 ms, MUST NOT BLOCK
    | submit heavy op
    v
PCI config workqueue (preallocated 1024-item pool)  ->  worker on PE2 (one per controller):
    engine start/enable | VQ create/config | CVQ IO-ctx | controller cleanup |
    hotplug create/destroy | MQ start (<=2 concurrent) | diagnostics/stats
Any operation that can block on firmware/DOCA transitions is moved off PE1, or the host's non-posted reads stall (Linux probe/reboot soft-lock).
Reset safety: per-device reset generations, cancel flags, VQ-shadow snapshots, bounded waits.
Initialization Process
The initialization process is:
-
Parse command line arguments.
-
Allocate and initialize
tlp_context. -
Open the DOCA device by IB device name or PCI address.
-
Create PE1 for TLP progress.
-
Configure optional CPU affinity.
-
Initialize the PCI config workqueue.
-
Verify VNet PCI TLP support.
-
Create the VNet PCI TLP type.
-
Attach the DOCA device to the PCI type.
-
Configure MSI-X count and doorbell count.
-
Start the PCI type.
-
Query and validate the predefined VirtIO-net BAR layout.
-
Create and configure the TLP channel.
-
Connect the TLP channel to PE1 and start it.
-
Initialize software PCI topology.
-
Initialize DOCA VNet subsystem.
-
Create VirtIO-net device models.
-
Create endpoints immediately in static mode, or defer endpoint creation in hotplug mode.
-
Allocate per-endpoint transaction regions.
-
Create one worker PE per controller.
-
Enter the progress loop.
Reset and Shutdown
Reset is triggered when the host writes device_status = 0.
The app:
-
Marks the device as canceling in-progress worker operations.
-
Increments the per-device reset generation.
-
Reinitializes VirtIO queue shadow state.
-
Holds
device_statusatNEEDS_RESETwhile controller cleanup is pending. -
Disables/stops/destroys VQs.
-
Stops and destroys the CVQ IO context when needed.
-
Keeps the offload engine object alive for normal driver rebind.
-
Destroys the offload engine only during endpoint destruction or final shutdown.
Shutdown:
-
Stops accepting new workqueue items.
-
Waits for outstanding work and MQ-start threads.
-
Destroys VirtIO device models.
-
Destroys endpoint controllers, TLP devices, and representors.
-
Flushes ACG credits.
-
Stops and destroys the TLP channel.
-
Stops/destroys PCI type and DOCA VNet subsystem.
-
Destroys worker PEs and PE1.
-
Frees
tlp_context.
DOCA Libraries
The application uses:
-
DOCA DevEmu PCI TLP: PCIe TLP channel, PCI type, TLP devices, ACG, MSI/MSI-X support.
-
DOCA DevEmu VNet: VirtIO-net offload engine, RX/TX VQs, CVQ, counters.
-
DOCA DevEmu VirtIO: generic VirtIO offload engine and VQ lifecycle APIs.
-
DOCA PE: progress engines for TLP and worker-side asynchronous operations.
-
DOCA Arg Parser: command-line parsing.
-
DOCA Log: application and SDK logging.
-
libibverbs: used by build and live update/device handling paths. -
Optional
libbsd: used forstrlcpywhen available.
Dependencies
Required:
-
BlueField platform with DOCA DevEmu VNet PCI TLP support.
-
DOCA SDK including DevEmu support.
-
libibverbs. -
Firmware/device support for VirtIO-net BAR layout.
-
PCI switch/TLP emulation enabled in firmware.
The app checks that the VNet TLP type is supported and that the TLP channel exposes exactly one NV switch TLP DSP. If not, initialization fails and asks for firmware configuration adjustment.
Unlike the vblk refapp, this code does not create application-managed DMA buffer pools or hugepage-backed data buffers for packet data. Packet movement is handled by DOCA VNet offload.
Compiling the Application
Compiling All Applications
cd /opt/mellanox/doca/applications/
meson setup /tmp/build && ninja -C /tmp/build
Compiling Only the Current Application
cd /opt/mellanox/doca/applications/
meson setup /tmp/build -Denable_all_applications=false -Denable_vnet_pci_dev=true && ninja -C /tmp/build
Alternatively, edit applications/meson_options.txt:
-
Set
enable_all_applicationstofalse. -
Set
enable_vnet_pci_devtotrue.
Then run the normal meson && ninja build.
Build Outputs
The build produces one executable:
doca_vnet_pci_dev
Typical output path:
/tmp/build/vnet_pci_dev/doca_vnet_pci_dev
Live update is implemented inside the same executable through --lu-mode; there are no separate *_lu and *_emu binaries in the current vnet app.
Running the Application
Prerequisites
A typical setup must enable TLP and PCI switch emulation in firmware. The code expects one NV switch TLP downstream port.
Example firmware configuration pattern:
mlxconfig -y -d /dev/mst/mt41692_pciconf0 reset
mlxconfig -y -d /dev/mst/mt41692_pciconf0 set TLP_EMULATION_NUM_PF=32
mlxconfig -y -d /dev/mst/mt41692_pciconf0 set TLP_EMULATION_ENABLE=1
mlxconfig -y -d /dev/mst/mt41692_pciconf0 set PCI_SWITCH_EMULATION_ENABLE=1
mlxconfig -y -d /dev/mst/mt41692_pciconf0 set PCI_SWITCH_EMULATION_NUM_TLP_PORT=1
mlxconfig -y -d /dev/mst/mt41692_pciconf0 set PCI_SWITCH_EMULATION_NUM_PORT=2
# SR-IOV supported up to 1k VFs, thus need set 1088 TOTAL_SF (1024 + 32 + 32).
mlxconfig -y -d /dev/mst/mt41692_pciconf0 s PF_BAR2_ENABLE=0 PER_PF_NUM_SF=1 PF_SF_BAR_SIZE=8 PF_TOTAL_SF=1088
Cold-reboot is required after firmware configuration changes.
* Core Isolation
Isolate the CPU core by Linux param (On DPU) like: isolcpus=14-15 nohz_full=14-15 rcu_nocbs=14-15 to avoid DPU core unstable impact. Need update-grup2 then reboot the DPU.
Strongly recommended to run ref app using the isolated cores like ./doca_vnet_pci_dev ... --worker-core 14 --tlp-core 15.
Application Usage
Usage: doca_vnet_pci_dev [DOCA Flags] [Program Flags]
Common DOCA flags include:
-
-h, --help -
-v, --version -
-l, --log-level -
--sdk-log-level -
--log-filter -
-j, --json
Program flags are described in the Command Line Flags section below.
Example Command Line Execution
Run with defaults in hotplug mode (-H 1):
./doca_vnet_pci_dev [-H 1] --worker-core 14 --tlp-core 15
Run in static mode (-H 0) with 4 endpoints and 16 max queue pairs each:
./doca_vnet_pci_dev -H 0 -n 4 -q 16 --worker-core 14 --tlp-core 15
Run with custom MAC, MTU, and speed:
./doca_vnet_pci_dev -H 0 -n 1 -m 52:54:00:12:34:56 -t 9000 -s 100000 --worker-core 14 --tlp-core 15
Run with explicit CPU affinity:
./doca_vnet_pci_dev -H 0 -n 16 --worker-core 14 --tlp-core 15 --mq-core 13
Run with SR-IOV (4 PF x 4 VF x 4 QP):
./doca_vnet_pci_dev -H 0 -n 4 --total-vfs 4 -q 4 --worker-core 14 --tlp-core 15
Run in live update active mode(-H 0 for static mode, -H 1 for hotplug mode):
./doca_vnet_pci_dev -H 0 --lu-mode active --worker-core 14 --tlp-core 15
Run a standby process for live update:
./doca_vnet_pci_dev -H 0 --lu-mode standby --worker-core 14 --tlp-core 15
Run with MRG_RXBUF and GUEST_CSUM features enabled (driver need to negotiate)
./doca_vnet_pci_dev -H 0 -t 9000 --mrg-rxbuf --guest-csum --worker-core 14 --tlp-core 15
Runtime Commands
Available through stdin:
-
plug <DSP_IDX>: create and hotplug an endpoint into a DSP slot. Hotplug mode only. -
unplug <DSP_IDX>: request hot-unplug of the endpoint in a DSP slot. Hotplug mode only. -
speed <EP_IDX> <Mbps>: update the reported link speed and raise a config-change MSI-X notification. -
sfinfo [<EP_IDX>]— Dump the SF representor (netdev name and ifindex) of one PF and its VFs, or of every PF when the index is omitted. At debug log level it also prints the representor'svhca_idandsf_index(SF numbering: §7.4). Use the printed ifindex to attach the representor to the OVS bridge. This is queried on demand rather than at bring-up to keep endpoint creation cheap.
Examples:
plug 0
unplug 0
speed 0 25000
sfinfo 0
Verifying the Device (Host Side)
After startup or hotplug:
lspci | grep -i virtio
ip link
Inspect queue support:
ethtool -l <interface>
Change active queue pairs:
ethtool -L <interface> combined 4
Inspect link information:
ethtool <interface>
Command Line Flags
General Flags
The app uses DOCA Arg Parser, so standard DOCA flags are available:
-
-h, --help: print usage. -
-v, --version: print version. -
-l, --log-level: set application log level. -
--sdk-log-level: set SDK log level. -
--log-filter: filter logs by module. -
-j, --json: parse flags from JSON.
Program Flags
-
-p, --pci-addr: DOCA device PCI address. Default:0000:03:00.0. -
-d, --ibdev-name: IB device name. Overrides--pci-addr. -
-m, --mac-addr: base MAC address. Default:52:54:00:12:34:56. -
-t, --mtu: MTU, range68-9000. Default:1500. -
-s, --speed: link speed in Mbps. Default:100000. -
-D, --duplex: duplex mode,0half or1full. Default:1. -
-q, --max-queue-pairs: maximum queue pairs, range1-127. Default:8. -
-z, --queue-size: queue size, power of two, range16-4096. Default:1024. -
-n, --num-ep: number of endpoints, range1-32. Default:1. -
-H, --hotplug-mode:1hotplug,0static. Default:1. -
--vf-queue-pairs— Queue pairs per VF, comma-separated (for example1,2,3,4). Applied to each PF's VF slots in turn and repeated once the list is exhausted. Requires--total-vfs > 0. When omitted, every VF inherits the PF's--max-queue-pairs. -
--admin-queues— Admin queue count.0disables the admin VQ,1enables one. Default0. Ignored (and force-disabled with a warning) in LU mode. -
--tlp-core: CPU core for the main TLP progress thread, or-1for auto. -
--worker-core: CPU core for the PCI config worker thread, or-1for auto. -
--mq-core: CPU core for MQ start threads, or-1for auto. -
--lu-mode: live update mode:none,active, orstandby. Default:none.
Validation rules:
-
--tlp-coremust not equal--worker-corewhen both are explicitly set. -
--mq-coremust not equal--tlp-corewhen both are explicitly set. -
--queue-sizemust be a power of two. -
--mac-addrlast octet must leave enough room for per-endpoint incrementing. -
--vf-queue-pairsrequires--total-vfs > 0; the app exits otherwise. -
A
--vf-queue-pairslist longer than--total-vfsis accepted, but the surplus entries are never handed out and the app warns. -
Admin queues and
--lu-modeare incompatible: LU mode disables the admin VQ with a warning rather than failing.
Optional Features Flags
-
--guest-csumDriver handles packets with partial checksum (VIRTIO_NET_F_GUEST_CSUM) -
--guest-tso4Driver can receive TSOv4 (VIRTIO_NET_F_GUEST_TSO4) -
--guest-tso6Driver can receive TSOv6 (VIRTIO_NET_F_GUEST_TSO6) -
--guest-ecnDriver can receive TSO with ECN (VIRTIO_NET_F_GUEST_ECN) -
--guest-ufoDriver can receive UFO (VIRTIO_NET_F_GUEST_UFO) -
--host-ecnDevice can receive TSO with ECN (VIRTIO_NET_F_HOST_ECN) -
--host-ufoDevice can receive UFO (VIRTIO_NET_F_HOST_UFO) -
--mrg-rxbufDriver can merge receive buffers (VIRTIO_NET_F_MRG_RXBUF)
Troubleshooting
Common issues:
-
VNet TLP type unsupported: the device or firmware does not expose VirtIO-net emulation support.
-
Wrong TLP port count: the app expects exactly one NV switch TLP DSP.
-
Host does not see devices: verify firmware settings, run PCI rescan, and confirm the app is in static mode or that
plug <idx>was issued. -
Hotplug command rejected: host hotplug interrupt may not be enabled yet, or a previous unplug is still in progress.
-
Queue startup takes time with high
--max-queue-pairs: MQ expansion is intentionally deferred and backgrounded. -
RSS/hash CVQ commands fail: the app does not implement those CVQ commands.
-
Host stalls during development changes: keep slow DOCA operations off PE1; the existing workqueue design is there to avoid PCIe completion timeouts.
Application Code Flow
Framework Initialization
Initialization Flow
-
main()initializes logging. -
doca_argp_init()initializes argument parsing. -
register_vnet_pci_dev_params()registers application-specific flags. -
doca_argp_start()parses CLI/JSON input. -
Signal handlers are installed for
SIGINTandSIGTERM. -
vnet_pci_dev_run()receives the parsed config. -
init_tlp_context()allocates topology state. -
find_doca_device()opens the DOCA device by IB name or PCI address. -
init_progress_engine()creates PE1. -
vnet_pci_device_configure_affinity()records affinity preferences. -
init_virtio_network_device()initializes PCI/TLP, topology, VNet, VirtIO device state, and endpoint creation. -
Worker PEs are created and attached to the PCI config workqueue.
-
run_progress_loop()starts processing TLPs, runtime commands, MSI retries, and LU triggers.
Key Points
-
PE1 is reserved for TLP handling and must remain responsive.
-
Heavy operations are submitted to the PCI config workqueue.
-
Worker PEs are created per controller so multi-endpoint operations can progress independently.
-
In LU standby mode, device and channel restore alter the normal open/start flow.
Resource Management
Resource Management Flow
Main resources:
-
tlp_context -
DOCA device handle
-
PE1 main progress engine
-
VNet PCI TLP type
-
TLP channel
-
ACG credit queue
-
software PCI device configs
-
BDF map
-
VirtIO device models
-
VNet controller array
-
per-controller worker PEs
-
per-controller offload engine
-
RX/TX/CVQ objects
-
VNet IO context for CVQ
-
stats/counters handles
-
per-endpoint transaction region memory
-
PCI config workqueue and work-item pool
Resource creation order:
-
Allocate
tlp_context. -
Initialize locks, maps, endpoint arrays, and controller arrays.
-
Open DOCA device.
-
Create PE1.
-
Initialize PCI config workqueue.
-
Create/start PCI type.
-
Create TLP channel.
-
Initialize topology and VNet subsystem.
-
Create VirtIO device models.
-
Create endpoints if static mode.
-
Allocate transaction regions.
-
Create worker PEs.
-
Create offload/VQ/IO resources lazily as the host reaches VirtIO states.
Key Points
-
The workqueue uses a preallocated pool of 1024 work items to avoid hot-path allocation.
-
MQ start concurrency is limited to 2 to avoid memory pressure and firmware command saturation.
-
Reset generation fields prevent stale async work from affecting a post-reset device.
-
Endpoint read/write locks protect TLP handlers from hotplug destruction races.
-
Diagnostics run on the worker side, not PE1.
PCI Switch Topology and Device Configuration
PCI Switch Topology Flow
-
init_device_topology()initializes all bridge and endpoint config structures. -
USP is configured as a Type 1 bridge with upstream-port PCIe capability.
-
Each DSP is configured as a Type 1 bridge with downstream-port and hotplug slot capabilities.
-
Each endpoint is configured as a Type 0 network device.
-
The dummy device is configured for unsupported request handling.
-
In static mode,
create_all_devices()creates endpoint representors and TLP devices. -
In hotplug mode,
create_device()is called later from the hotplug work item. -
Host enumeration assigns bus numbers and BDFs.
-
BDF mappings are cached and updated if the host renumbers buses.
Endpoint creation flow:
-
Create or reattach a representor.
-
Query representor VHCA ID.
-
Create the TLP device.
-
Start the TLP device.
-
Create the VNet controller and offload engine.
-
Mark endpoint present.
Key Points
-
DSP count equals endpoint count.
-
Each DSP supports PCIe hotplug slot behavior.
-
Hotplug signaling uses attention button and slot status bits.
-
MSI for hotplug is sent as a Memory Write TLP using ACG credits.
-
If ACG credits are exhausted, MSI retry is scheduled.
-
Static mode sets slots to powered-on and link-active at startup.
Virtio-net Controller
Controller Initialization Flow
Controller creation happens in vnet_pci_dev_vnet_controller_create():
-
Resolve endpoint PF index.
-
Associate controller with the per-endpoint VirtIO device.
-
Convert TLP device to PCI endpoint.
-
Create a VNet offload engine, or import one during LU standby.
-
Configure MTU.
-
Configure MAC address.
-
Configure total number of queues.
-
Initialize controller atomics and deferred MQ state.
-
Allocate RX and TX VQ pointer arrays.
-
Query/log SF representor information.
-
Wait for host
FEATURES_OKbefore starting hardware preparation.
On FEATURES_OK:
-
Validate driver features vector.
-
Determine if
VIRTIO_NET_F_CTRL_VQandVIRTIO_NET_F_MQwere negotiated. -
Set initial active queue pairs.
-
Submit offload engine start.
-
Submit VQ object creation.
-
Submit CVQ IO context creation.
On DRIVER_OK:
-
Submit start-and-enable work.
-
Enable optional features if negotiated.
-
Snapshot VQ shadow config.
-
Configure RX/TX/CVQ VQs.
-
Start VQs.
-
Bind CVQ to IO context.
-
Enable VirtIO offload engine.
-
Create stats/counter resources.
Virtio Queue Lifecycle State Machine
Conceptual state flow:
UNCREATED --FEATURES_OK--> CREATED --host cfg--> CONFIGURED --start--> STARTED --enable--> ENABLED
   ^                                                                                        |
 DESTROYED <- STOPPED <- DISABLED <----------------- reset / group-disable -----------------+
Lifecycle by phase:
-
UNCREATED: no DOCA VQ object exists. -
CREATED: RX/TX/CVQ object has been created afterFEATURES_OK. -
CONFIGURED: host-provided queue size, MSI-X vector, descriptor address, driver address, and device address have been applied. -
STARTED:doca_devemu_virtio_vq_start()has completed. -
ENABLED: offload engine or VQ group enable has made the queue operational. -
DISABLED: VQ group or engine disable has stopped host-visible processing. -
STOPPED: VQ stop completed. -
DESTROYED: VQ object destroyed.
Key Points
-
RX/TX VQs are created for the configured maximum queue pairs.
-
CVQ is created only when MQ is negotiated.
-
Data queues may be deferred during multi-endpoint startup so enumeration can settle.
-
Increasing queue pairs completes the CVQ request immediately, then starts extra queues in background.
-
Decreasing queue pairs disables and stops extra queues synchronously.
-
Worker readers use snapshots of VQ shadow config to avoid reset races.
-
SF numbering. Each function's offload engine is backed by its own SF:
-
PF: 1000–1999, in both static and hotplug mode (firmware 32.50.0346 or later).
-
VF: 3000–5999.
-
Each new engine takes the lowest free number in its range. Numbers therefore follow creation order: EP index at startup in static mode,
plugorder in hotplug mode, and each VF's firstFEATURES_OK. -
A live upgrade keeps every function's number. Re-creating an engine can assign a different one, as a function recycle does (§7.11, including a host driver rebind, which drops BME) and as a VF's next
FEATURES_OKdoes. Re-check withsfinfobefore re-attaching OVS ports.
-
I/O Request Processing
I/O Request Processing Flow
For packet data:
-
Host
virtio_netdriver posts RX buffers and TX descriptors. -
Host notifies queues through the VirtIO notify region.
-
DOCA VNet offload processes packet datapath using the configured VQs.
-
The application does not copy packet payloads in userspace.
-
Completion and interrupt behavior are handled through the DOCA VNet/VirtIO offload path.
For CVQ control requests:
-
Host submits a control command on CVQ.
-
DOCA VNet forwards the request to the registered IO context.
-
Worker PE progresses the IO context.
-
vnet_pci_dev_ctrl_req_handler()receivesclsandcmd. -
MQ pair-set commands are handled by the app.
-
MAC/RX/VLAN classes are acknowledged as backend-handled.
-
Unsupported classes/commands return
VIRTIO_NET_ERR. -
The request is completed with
doca_devemu_vnet_ctrl_req_complete().
Key Points
-
RX/TX data path is hardware/offload driven.
-
CVQ is the main application-visible I/O request path.
-
MQ expansion avoids blocking the host by completing the CVQ command before long VQ startup.
-
RSS/hash CVQ commands are not implemented by the app.
-
The app’s most important responsibility is correct lifecycle sequencing, not packet processing.
Device Lifecycle Management
Device Lifecycle State Machine
Endpoint-level conceptual state:
Endpoint: INIT -> MODEL_CREATED -> ENDPOINT_CREATED -> FEATURES_OK_PREP -> DRIVER_OK_ENABLE -> OPERATIONAL -> RESETTING -> CLEANED_FOR_REBIND -> (rebind) | DESTROYED
Hotplug state:
Hotplug : ABSENT --plug--> PRESENT(link down) --Power-ON--> DLActive --> OPERATIONAL
             ^                                                              | unplug
          DESTROYED <- delayed destroy <- Power-OFF (or 30s timeout) <- UNPLUG_PENDING
Hotplug Management Flow
Plug:
-
Runtime command
plug <idx>is parsed. -
Workqueue receives hotplug work.
-
The endpoint representor, TLP device, and VNet controller are created.
-
DSP slot status sets attention button, presence detect changed, and presence detect state.
-
MSI is sent if ACG credit and host MSI setup are available.
-
Host
pciehpnotices the slot event. -
Host powers on the slot.
-
TLP handler observes Slot Control Power ON and sets
DLActive. -
Host enumerates and probes the VirtIO-net endpoint.
Unplug:
-
Runtime command
unplug <idx>is parsed. -
Workqueue marks endpoint
pending_unplug. -
DSP slot status raises attention button.
-
MSI is sent or retried.
-
Host
pciehpunbinds the driver and powers off the slot. -
TLP handler observes Slot Control Power OFF.
-
Delayed destroy work is submitted.
-
Controller, TLP device, and representor are destroyed.
-
Pending flags are cleared.
If the host never powers off the slot, the main loop forces removal after UNPLUG_TIMEOUT_SEC, currently 30 seconds.
Key Points
-
Hotplug creation is intentionally done on the workqueue because endpoint creation can take hundreds of milliseconds.
-
PE1 must keep progressing TLPs during hotplug.
-
Plug and unplug use PCIe hotplug slot semantics rather than ad hoc host signaling.
-
Unplug waits for host power-off before destroying resources.
-
A timeout safety net handles failed or stuck host removal.
SR-IOV
One emulated PF exposes up to 64 independent virtio-net VFs, each with its own config space, MSI-X vectors, doorbells, offload engine and SF datapath.
VFs can be driven by the host or passed through to a VM.
Off by default; enabled with --total-vfs <1..64>.
Code split:
-
vnet_sriov.c-- capability probe, VF-index pool, PF representor with reserved range, VF representor discovery, slot provisioning and exposure. -
vnet_pci_device.c-- SR-IOV extended-capability synthesis and write decode, VFE fan-out, per-VF config/MMIO TLP routing. -
vnet_pci_dev_core.c-- per-VF offload engine and datapath. -
vnet_recycle.c-- per-VF FLR / BME / PERST reset.
Four stacked lifetimes
A VF has four independent lifetimes. Expensive work is pushed into the longest-lived layer so that the host's sriov_numvfs write — which runs against a bounded PCIe enumeration window — costs almost nothing.
|
Layer |
Created |
Destroyed |
Holds |
|---|---|---|---|
|
PF create |
PF destroy |
firmware VF object |
|
PF bring-up |
PF teardown |
MSI-X + doorbell claims |
|
VFE 0→1 |
VFE 1→0 |
answers host TLPs |
|
guest FEATURES_OK |
reset / FLR / VFE 0 |
the datapath |
Layers 1 and 2 are built once, before the host has any visibility. Layer 3 is a single atomic_bool. Layer 4 is built by the guest driver.
Phase A — capability probe and validation
vnet_sriov_probe_caps() gates on doca_devemu_pci_tlp_cap_type_is_dynamic_sriov_supported(). If the device does not advertise dynamic SR-IOV, or firmware reports a dynamic-VF pool size of 0, the app falls back to the non-rep_ex create path.
vnet_sriov_validate_caps() then applies four independent limits. Each catches a configuration the others miss:
|
Check |
Limit |
Catches |
|---|---|---|
|
Per-PF VF count |
64 |
one oversized PF |
|
Single-bus ARI fit |
function number ≤ 255 |
|
|
Aggregate VF-VQ footprint |
5120 VQs (16 PF × 64 VF × 5 VQ) |
few VFs each with many queue pairs |
|
Aggregate VF count |
1024 (16 PF × 64 VF) |
many PFs each with few queue pairs |
The VQ-budget check exists so that an over-subscribed configuration is rejected at init rather than failing a VQ start after the guest has already written DRIVER_OK, which can wedge the host.
Per-VF resources are VNET_SRIOV_VF_NUM_MSIX(qp) = 2*qp + 2 and VNET_SRIOV_VF_NUM_DB(qp) = 2*qp + 1 — one doorbell per virtqueue, and one MSI-X vector per virtqueue plus one for config changes.
Phase B — PF creation reserves a VF index range
Inside create_device(), the SR-IOV path reserves before it creates. A reservation failure is fatal by design: falling back to a plain representor would advertise an SR-IOV capability with no VF backing, i.e. phantom VFs.
The pool is a cursor allocator with a LIFO rewind fast path. Once every reserved range is released the cursor resets to zero, so multi-PF teardown in any order strands no indices.
The reserved base is passed to doca_devemu_pci_type_create_rep_ex() as first_dynamic_vf_idx, together with TotalVFs, stride 1, first-VF-offset 1, and the initial per-VF MSI-X/doorbell counts.
Two VF indices coexist. The SDK's
vf_indexis PF-relative. The application'sslot->vf_indexis globally unique (first_vf_idx + PF-relative index) and is what the per-VF MAC derivation uses. Confusing the two produces duplicate MACs across PFs.
Phase C — discover, pool, provision (host still sees nothing)
-
vnet_sriov_discover_vf_reps()walks the emulated-representor list and keeps entries whose parent PF VUID matches this PF, opening each intovf_slots[]. Gaps, duplicates and unrelated entries are tolerated; only infrastructure failures unwind. -
vnet_sriov_reset_vf_resources()returns the PF's VF MSI-X and doorbell allocation to the dynamic pool viadoca_devemu_pci_ep_reset_msix_resources()/_reset_db_resources(). One-shot and order-sensitive: it only runs with--vf-queue-pairs, and is refused once any VFtlp_devhas started. -
vnet_sriov_provision_vf_slots()creates and starts atlp_devper slot, each claiming its own counts. Sizing must land between create and start, the same pre-start rule that applies to the PF.
Unwinding is deliberately asymmetric: with per-VF sizing a provisioning failure is fatal to the PF, because a partly consumed pool cannot be reclaimed. Without per-VF sizing the PF keeps whatever slots succeeded.
At the end of this phase every VF exists in firmware, holds its resources, and is invisible to the host.
Phase D — host writes VFE, fan-out exposes
The SR-IOV Control write is decoded on the TLP thread. merged_ctrl is committed immediately so the host observes the new state, and the fan-out is queued to the worker.
Two asymmetries matter:
-
Enable sweeps
NumVFs; disable sweepsTotalVFs. If the host enabled 32 VFs and later re-enabled with 8, a disable must still reach slots 8–31 left visible by the earlier largerNumVFs. -
The VF config-space reset on disable runs inline on the TLP thread, not on the worker, because it has to be ordered ahead of the host's re-probe.
VFE_FAN_OUT_START is the one work type permitted to overtake other PFs' queued work, because the host's sriov_numvfs write has a bounded completion window. Ordering within a PF is preserved.
Phase E — host enumerates the VFs
VFs are not function-0 endpoints, so BDF lookup cannot resolve their Routing IDs and they fall through to the dummy device. The dummy handler re-resolves them with find_vf_slot_by_bdf() and serves from the VF's own emulated image.
For the window where VFE is set but fan-out has not yet reached a slot, the app returns Configuration Request Retry Status so the root complex retries instead of reading an invalid header and failing with EIO.
CRS is gated on VFE = 1. With VFE clear the same probe falls through to Unsupported Request, which keeps boot and reboot VF-range scans fast.
Phase F — guest driver brings up the datapath
From here a VF mirrors a PF, driven from handle_vf_mmio_write():
-
FEATURES_OK 0→1 — validate features, latch whether
F_CTRL_VQ + F_MQwere negotiated, queueVF_ENGINE_SETUP. The worker callsdoca_devemu_vnet_offload_engine_create()on the VF's own endpoint, sets shm path / MTU / MAC /num_queues, and starts it. -
DRIVER_OK 0→1 — queue
VF_ENGINE_ENABLE: start the VQs, bind the CVQ, enable the engine. -
status → 0 — reset the shadow inline so the re-probe's
queue_enable0→1 edges re-fire, and queue the heavy teardown. FIFO ordering places the teardown before the re-probe's setup.
Unlike the PF, whose engine is created eagerly in create_device(), the VF engine is created lazily on FEATURES_OK.
If the guest drives FEATURES_OK or DRIVER_OK while the VF is recycling, bring-up is refused and latched in deferred_setup_status / deferred_setup_pending. The guest will never repeat those edges, so the recycle owes the VF a bring-up on the way out.
Reset paths
|
Trigger |
Action |
Engine afterwards |
|
|---|---|---|---|
|
Guest |
shadow reset inline, teardown queued |
destroyed |
untouched |
|
FLR / BME 1→0 / PERST |
full recycle (see §7.11) |
not rebuilt |
stop → start |
|
VFE 1→0 |
unexpose |
destroyed |
untouched |
The VF recycle deliberately omits the rebuild callback the PF has, because a VF has no engine of its own until the guest's next FEATURES_OK builds one. vnet_vf_recycle_is_present() treats a VF as gone as soon as active clears, since clearing VF Enable legitimately removes the function long before the slot array is freed.
None of the three paths touches the tlp_dev, so its MSI-X and doorbell claims survive and repeated enable/disable cycles stay cheap.
PF teardown
Ordering is forced by reference counting: VF devices must stop before VF representors close, because a started VF tlp_dev holds a reference on its representor. The PF then releases its pool range only if owns_pool_range is set — an LU-restored PF reattached to an existing range without reserving it, and releasing would corrupt the allocator in the process that does own it.
Operational constraints
-
A PF cannot be hot-unplugged while VFE is set or any VF datapath is live. The unplug is rejected with
... (VFE=1, K live VF datapath(s)); disable it on the host first. Yanking a PF under live VFs is a surprise removal that can fault a VM holding one through VFIO. -
Set
sriov_numvfs = 0and shut down any VM holding a VF before rebooting the host. Rebooting with VFE set leaves stale VF state on the DPU that can disrupt the next enumeration. -
Each VF representor must be added to the OVS bridge before it carries RX traffic:
ovs-vsctl add-port ovsbr1 <vf_representor>. Usesfinfoto get the ifindex. -
VF pass-through: bind to
vfio-pcion the host with IOMMU enabled; the VF enumerates as1af4:1041. -
Per-VF MACs are
base_low16 + num_ep + vf_index. PFs occupy[0, num_ep). The value wraps if the base MAC's low 16 bits are withinnum_ep + total_vfsof0xFFFF, so choose a base MAC with headroom in the low bytes.
Expected log sequence
Single PF, -q 8, --total-vfs N. Match on text, not line numbers.
SR-IOV: dynamic SR-IOV supported (max_total_vfs=.., pool_size=..)
SR-IOV: PF representor created with VF range [0, N) (vf_num_msix=18, vf_num_db=17)
SR-IOV: provisioned N of N VF slots ahead of the host enable
SR-IOV VFE: 0 -> 1 (NumVFs=N, TotalVFs=N)
SR-IOV VFE 0->1 fan-out: N/N slots exposed (0 unavailable)
SR-IOV: VF[slot=s, vf_index=g] FEATURES_OK - queueing engine bring-up (mq=1)
SR-IOV: VF[vf_index=g] offload engine created (idle, 17 VQs, MTU=1500)
SR-IOV: VF[slot=s, vf_index=g] DRIVER_OK - queueing engine enable
Note vf_num_db=17 (= 2*8 + 1), not 18. The doorbell and MSI-X counts differ by one.
Cleanup and Shutdown
Cleanup and Shutdown Flow
Shutdown begins when SIGINT or SIGTERM sets force_quit.
The main progress loop exits when:
-
Quit is requested and no hot-unplug is pending.
-
Hot-unplug pending has completed.
-
Hot-unplug pending times out.
-
LU handover is requested by
SIGUSR1.
Phase 1 – Worker and Device Cleanup
The current vnet app does not have vblk-style per-IO worker threads named like vblk_io_ctx_thread(). Its equivalent first phase is workqueue and controller-side cleanup.
Steps:
-
Disable worker-side diagnostics.
-
Shut down PCI config workqueue.
-
Join outstanding MQ start threads.
-
Stop accepting new work.
-
Destroy VirtIO device models.
-
For each endpoint, destroy controller resources.
-
Disable VQs while engine is enabled.
-
Disable engine.
-
Stop VQs.
-
Destroy VQs.
-
Stop and destroy CVQ IO context.
-
Stop offload engine.
-
Destroy offload engine when required.
-
Destroy TLP devices and representors.
-
Clear endpoint present state.
Phase 2 – Reverse-Order Resource Cleanup
After workqueue shutdown:
-
Clear worker PE references from the workqueue.
-
Destroy per-controller worker PEs.
-
Flush pending ACG credits.
-
Stop the TLP channel context.
-
Drain PE1 until the TLP channel reaches idle or timeout.
-
Destroy the TLP channel.
-
Stop and destroy the PCI type.
-
Tear down DOCA VNet.
-
Remove the DOCA device from VNet.
-
Destroy PE1.
-
Free transaction regions, BDF maps, topology arrays, controller arrays, and VirtIO device arrays.
-
Close LU connections if any.
-
Destroy ARGP resources in
main().
Key Points
-
Cleanup order follows ownership dependencies.
-
Workqueue shutdown happens before freeing objects referenced by work items.
-
Worker PEs are destroyed only after the workqueue exits.
-
TLP channel is stopped and drained before destruction.
-
LU cleanup differs because the active process transfers traffic ownership before releasing local handles.
Live Upgrade (LU) Mode
The vnet refapp implements live update in the same binary through --lu-mode.
A(active) <- B(standby) connects -> A exports state + cmd FD -> B reconstructs device/EP/engines
from export blobs, replays VQ cfg (engines IDLE) -> B DEV_READY -> A DEV_GO -> B enables engines
-> B DEV_ACK -> TLP channel handover -> B active (chainable)
Modes:
-
none: normal operation. -
active: current traffic owner. -
standby: process that restores state from active and takes over.
LU uses:
-
Unix domain socket:
/tmp/vnet_live_update.sock. -
Lock file:
/tmp/vnet_live_update.lock. -
Shared memory:
/vnet_live_update. -
TLP channel shared memory directory:
/dev/shm/vnet_lu_channel. -
SIGUSR1to trigger active handover.
High-level LU flow:
-
Active process runs and serves traffic.
-
Standby process connects to active.
-
Active sends command FD and exports device state.
-
Standby opens shared memory and reconstructs DOCA device state.
-
Standby recreates endpoint/controller/offload objects from export blobs.
-
Standby replays VirtIO config and VQ state without enabling engines.
-
Standby signals
DEV_READY. -
Active sends final
DEV_GO. -
Standby enables engines, one or more in parallel.
-
Standby sends
DEV_ACK. -
Channel LU transfers the TLP channel.
-
Standby becomes active and can support another chained LU.
Static LU state includes:
-
endpoint VHCA ID
-
MAC/MTU
-
device features
-
max queue pairs
-
active queue pairs
-
queue size
-
MQ negotiation state
-
per-VQ descriptor/driver/device addresses
-
MSI-X vectors
-
offload engine export blobs
-
TLP channel configuration
Hotplug LU has additions:
-
Number of populated slots
-
Slot-presence bitmap
-
Base MAC used to reconstruct per-slot MAC addresses
Crash Recovery
The current vnet refapp has live update state transfer but does not implement a separate persistent crash recovery mechanism comparable to a full crash-resume feature.
Important distinction:
-
LU is coordinated and stateful: active and standby cooperate.
-
Crash recovery would require reconstructing after unexpected termination without a live handover.
-
The current code has robust cleanup, reset handling, timeout handling, and LU import/export paths, but no standalone crash recovery workflow is exposed as an application mode.
Function Recycle (FLR / BME / PERST)
PCIe-level resets invalidate a function's crossed mkey and MSI-X state, so the datapath must be rebuilt even though the function itself continues to exist.
Recycle preserves the function object and its config-space responder while destroying and rebuilding everything below it.
Triggers:
|
Trigger |
Config space reset? |
Notes |
|---|---|---|
|
FLR (PCIe Device Control bit 15) |
yes |
auto-cleared in the visible image immediately |
|
Bus Master Enable 1→0 |
no |
BME 0→1 releases a parked recycle rather than starting a new one |
|
PERST assert |
yes |
asserts |
State machine: IDLE → PENDING → SUSPENDED → [PARKED] → REBUILDING → IDLE, with a terminal FAILED.
-
PENDINGdestroys the datapath and stops thetlp_dev. -
PARKEDis entered when the link is down or BME is still clear, so restart must wait. -
REBUILDINGrestarts thetlp_devand rebuilds the datapath. PFs rebuild an engine here; VFs do not — the guest's next FEATURES_OK builds theirs. -
Restart failures retry every 10 ms up to 500 times; exhaustion moves to
FAILEDand publishesNEEDS_RESETto the host.
A re-trigger mid-flight ORs its reason into the existing mask and bumps a generation counter, so a second reset supersedes stale worker work instead of running a concurrent recycle.
The sweep runs on the TLP thread and only queues worker steps, keeping SDK and firmware round-trips off the config-request path.
vnet_recycle_abandon() distinguishes teardown from recycling: it invalidates queued generations and clears pending reports before normal destroy proceeds.
Virtio-net Operations Support Summary
Supported by the refapp/offload stack:
-
RX/TX packet queues: supported through DOCA DevEmu VNet offload after VQs are configured and engine is enabled.
-
Control virtqueue: supported when
VIRTIO_NET_F_CTRL_VQandVIRTIO_NET_F_MQare negotiated. -
Multi-queue pair set: implemented for
VIRTIO_NET_CTRL_MQ_VQ_PAIRS_SET. -
Runtime link speed update: supported through app command
speed <idx> <Mbps>and config-change MSI-X. -
Hotplug/unplug: supported through PCIe hotplug slot emulation.
Partially supported or backend-acknowledged:
-
MAC control class: acknowledged as backend-handled in the app callback.
-
RX control class: acknowledged as backend-handled in the app callback.
-
VLAN control class: acknowledged as backend-handled in the app callback.
Not implemented in the app callback:
-
RSS configuration command.
-
Hash configuration command.
-
Unknown MQ commands.
-
Unknown control classes.
Virtio Feature Bits Support Summary
Advertised by default:
-
VIRTIO_NET_F_MAC: device reports MAC address. -
VIRTIO_NET_F_STATUS: link status is available. -
VIRTIO_NET_F_CSUM: checksum offload feature advertised. -
VIRTIO_NET_F_MTU: MTU is reported. -
VIRTIO_NET_F_SPEED_DUPLEX: speed and duplex are reported. -
VIRTIO_NET_F_HOST_TSO4: host can send TSOv4 packets to device. -
VIRTIO_NET_F_HOST_TSO6: host can send TSOv6 packets to device.
Always added by device initialization:
-
VIRTIO_F_VERSION_1: modern VirtIO compliance. -
VIRTIO_F_ACCESS_PLATFORM: platform/IOMMU access semantics. -
VIRTIO_NET_F_CTRL_VQ: control virtqueue available. -
VIRTIO_NET_F_MQ: multi-queue support.
Defined but not part of the default advertised feature set unless code (SDK) is extended:
(some of the features are offered to enabled using CLI option)
-
VIRTIO_NET_F_GUEST_CSUM -
VIRTIO_NET_F_CTRL_GUEST_OFFLOADS -
VIRTIO_NET_F_GUEST_TSO4 -
VIRTIO_NET_F_GUEST_TSO6 -
VIRTIO_NET_F_GUEST_ECN -
VIRTIO_NET_F_GUEST_UFO -
VIRTIO_NET_F_HOST_ECN -
VIRTIO_NET_F_HOST_UFO -
VIRTIO_NET_F_MRG_RXBUF -
VIRTIO_NET_F_CTRL_RX -
VIRTIO_NET_F_CTRL_VLAN
Developer Notes
The main engineering theme in this refapp is latency isolation. PE1 must continuously progress PCI TLP completions, so any operation that can block on firmware or DOCA state transitions is moved to the PCI config workqueue or detached MQ-start threads.
The second key theme is reset safety. The app uses reset generations, cancellation flags, VQ shadow snapshots, and short bounded waits so stale worker operations cannot corrupt a newly reset device.
The third key theme is host compatibility. Hotplug follows PCIe slot semantics, VirtIO status transitions follow the expected driver lifecycle, and CVQ MQ commands are completed quickly to avoid Linux probe and soft-lockup issues.
Last updated: