

NVIDIA Minerva's log-based NLP/ML analysis detected a previously undetected ConnectX NIC PCI error that would have led to future job failures, allowing operators to remove the affected node from the allocation pool before any impact occurred.
Challenge
A ConnectX NIC PCI error was generating kernel-level warnings that did not surface through standard monitoring. Without proactive detection, the error would have propagated silently until it caused a job failure.
Proactive Detection
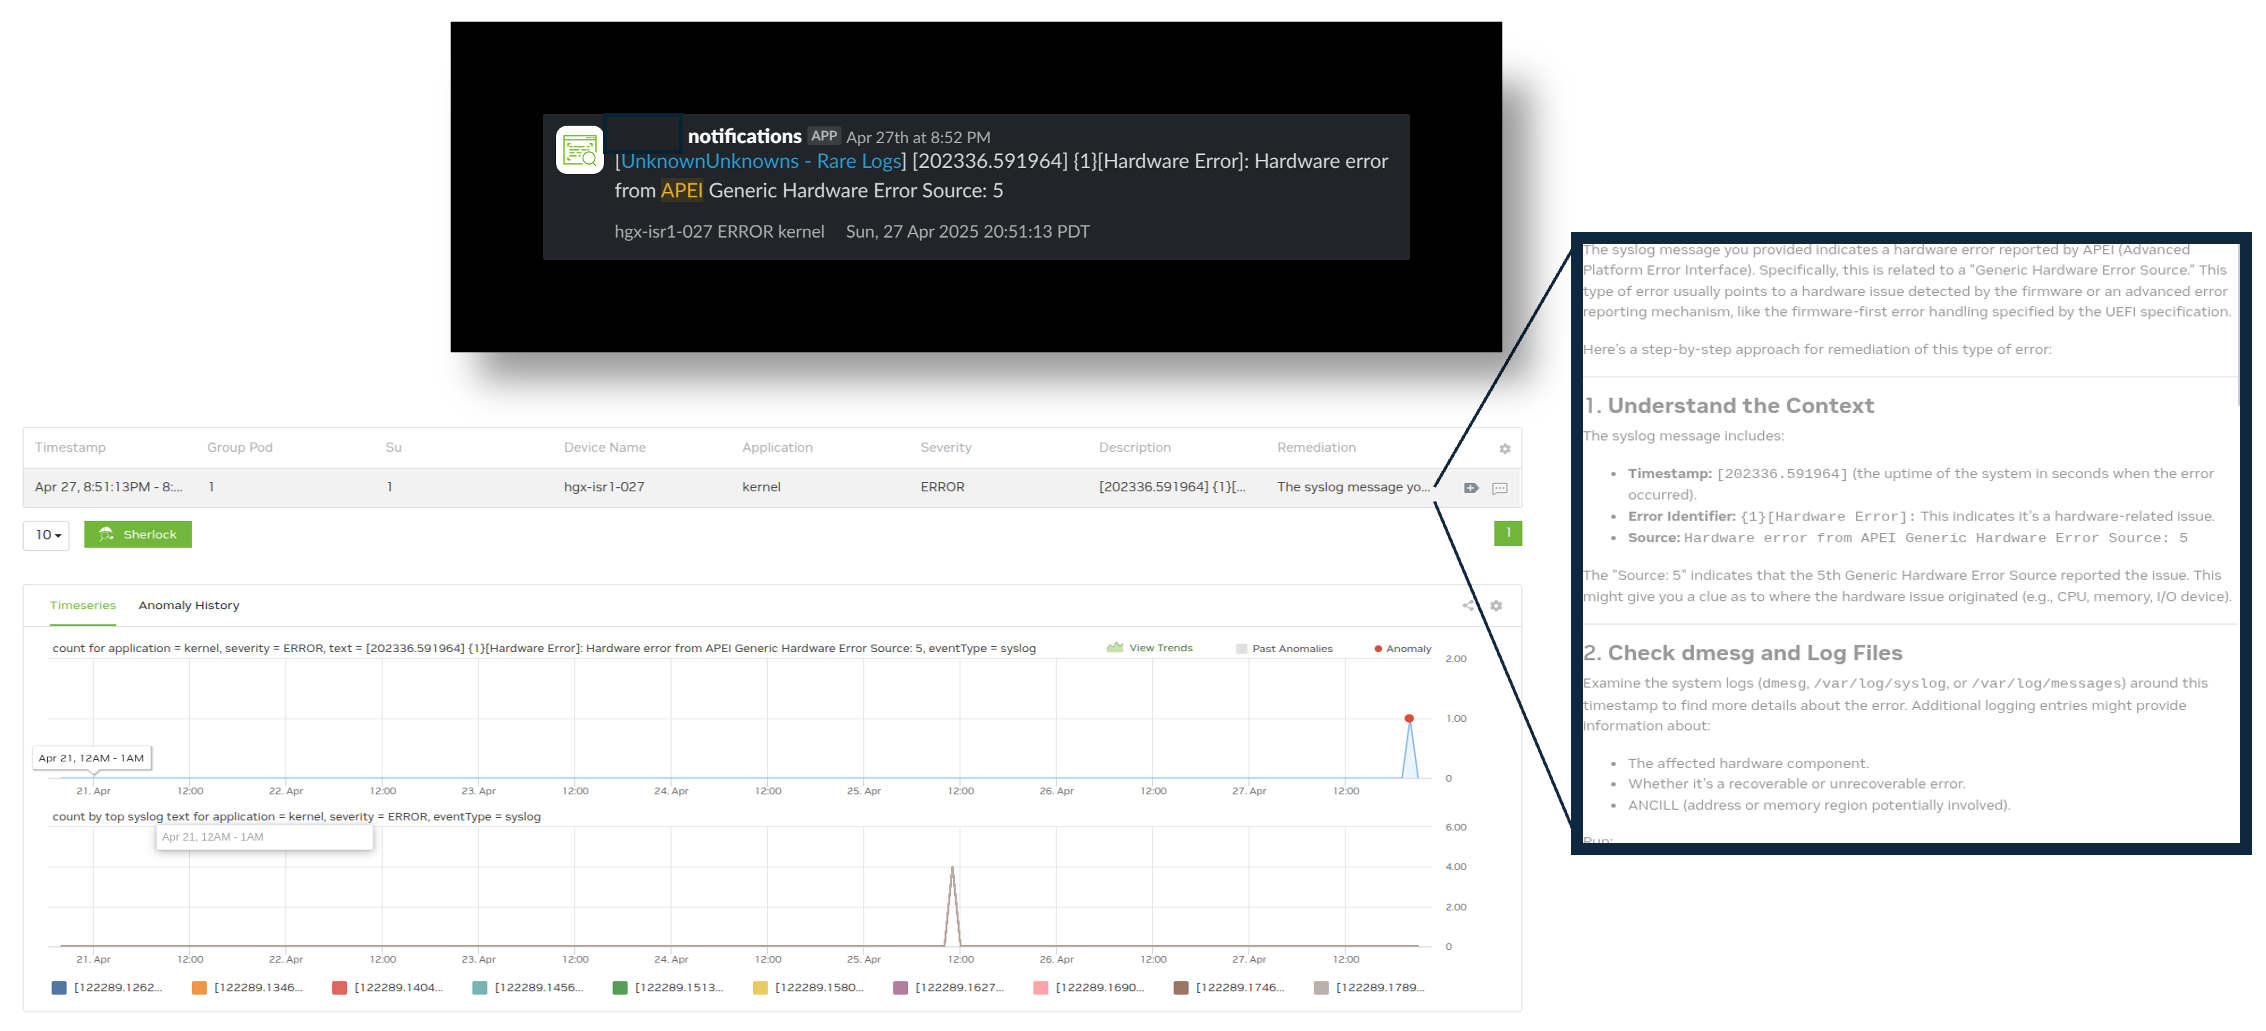
NVIDIA Minerva identified a potential issue with the NIC driver through NLP/ML analysis of system logs, surfacing the error as a Slack notification before it affected any running jobs.
Mitigation and Savings
-
The affected node was removed from the allocation pool, preventing impact on future jobs and increasing Mean Time to Failure (MTTF).
-
Estimated 922 hours of job runtime savings and 12 hours of node uptime savings.
-
Generative AI-assisted remediation steps helped reduce Mean Time to Resolution (MTTR).
Illustrative Workflow
-
NVIDIA Minerva surfaced a hardware error notification in Slack.
-
The alert was correlated to an ACPI Platform Error Interface (APEI) generic hardware error source.
-
System logs and anomaly views highlighted the PCI/NIC-related kernel issue.
-
Recommended remediation guidance helped operators investigate context, review logs, and reduce MTTR.
Operational Impact
-
Earlier detection of otherwise hard-to-identify hardware issues.
-
Reduced risk of downstream job failures.
-
Faster operational triage through guided remediation.
-
Measurable infrastructure efficiency and uptime improvements.
Last updated: